Predicting temperature-dependent solubility for solvent selection

During the summer of 2010 I reported on the Solvent Selector web service that Andrew Lang and I constructed. The idea was to flag potential solvents with a high solubility for the reactants and a low solubility for the product, so that the work-up would require a simple filtration.

If available, the Solvent Selector service uses measured solubility values. If not available, it attempts to predict the room temperature solubility using one of two models based on Abraham descriptors.

We now have modified the Solvent Selector so that it takes into account temperature. Andrew has inserted a thermometer icon next to each solvent in the report. When clicked, a plot is displayed over the entire range of temperatures where the solvent is a liquid. Curves for each starting material and the product are provided - and hovering over a data point provides numerical values.

There are several ways this resource could be used by chemists.

For reactions where some starting materials are not soluble enough at room temperature, the reaction could be carried out at a higher temperature. A higher temperature might also be desirable simply to speed up the reaction. Being able to predict the solubility of the product at that higher temperature would allow the course of the reaction to be monitored by the appearance of a precipitate.

For reactions where the solubility of the product is too high at room temperature, the curves could be used to estimate how low one could cool the reaction mixture without any chance that one of the starting materials would precipitate out. For example, consider the following Ugi reaction.


An optimization study was performed and found that methanol and ethanol provided much better yields than THF.(see JoVE article) This makes sense from a solubility standpoint, where the Ugi product room temperature solubility is less than 0.05 M for methanol and ethanol but is 0.26 M for THF Solvent Selector results)

However, by clicking on the thermometer icon for the THF entry, one gets the following temperature curves for solubility.

By hovering over the curve for the Ugi product we find that the predicted solubility in THF at -78C (conveniently a dry ice in acetone bath) is 0.01M, while that for the starting material boc-glycine is 0.65 M, well above the 0.5 M concentration at the start of the reaction. This means that even if the reaction did not take place to a significant extent, we would not expect the starting material to precipitate at -78C. Any precipitate should be the pure product.

Of course another obvious application is for solvent selection for re-crystallization.

How it works

For some time now we have been collecting literature on the temperature dependence of solubility in various systems (live Mendeley collection here - be patient it might take a minute to display). Although equations vary depending on the specific approach there seem to be the following commonalities:

  1. An assumption is made that miscibility is reached at the melting point of the solute.
  2. The log of the solubility is linearly proportional to the inverse of the temperature in Kelvin.

I have looked into a few examples that we have of solubility over a temperature range and the above do seem to hold. This means that with only a room temperature solubility and a melting point for a given solute, the solubility at any temperature can be interpolated or extrapolated. (The concentration at the miscibility point is calculated from the predicted density of the solute divided by its molecular weight).

Although there are situations where two liquids are not miscible because of extreme dissimilarity (e.g. methanol and hexane), for the most part our experience shows that the first assumption is valid. Also, we are not correcting for changes in density for the solute or solvent at different temperatures. Nevertheless, when only a single solubility measurement in a given solvent and a melting point are known, this simple model may prove to be of use as a rough guide for reaction design or re-crystallization. We'll report on its practicality over time as we put it to use.

Mirza PhD defense on the Ugi reaction for anti-malarial screening

My student Khalid Baig Mirza defended his Ph.D. thesis at Drexel University on December 6, 2010. It was nice to see all the pieces come together - even though there are still a few intriguing puzzles left to be fully resolved. Like most research projects, every answer generates several interesting additional questions and Khalid did a good job of showing what these key issues are for his work.

In his presentation, Khalid first discusses Open Notebook Science and his contribution to the sodium hydride oxidation controversy. Then he describes the UsefulChem project, involving the use of the Ugi reaction as an approach to synthesizing new anti-malarial agents, including a few unexpected side reactions and challenges. Finally he presents an overview of the ONS Solubility Challenge and its application to organic synthesis.

Visualizing Social Networks in Open Notebooks

Increasing the role of automation in the scientific process has long been a fundamental objective of Open Notebook Science. The automatic discovery of new connections in open scientific work is potentially a very important contribution to this end.

Visualizing social networks within and between Open Notebooks is certainly a good first step. Luckily, our Reaction Attempts project has already abstracted the key elements of organic chemical reactions within a collection of Open Notebooks. This means that creating connection maps between people and chemicals can be attempted with reliable and semantically unambiguous database sources.

The Reaction Attempts database records the identity of reactants and products as ChemSpiderIDs for each reaction within a collection of notebooks. Also the name of the researcher, the solvent, the yield (when available) and a few more key identifiers are recorded.

We are very fortunate that Don Pellegrino, an IST student at Drexel, has selected the analysis of networks within Open Notebooks as part of his Ph.D. work. He has started to report his progress on our wiki and is eager to receive any feedback as the work progresses (his FriendFeed account is donpellegrino).

Don's first report is available here. He is using the Open Source software Gephi for visualization and has provided all of the data and code on the associated wiki page. (also see Tony Hirst's description of mapping ONS work which provided some very useful insights) Don has provided a detailed report of his findings but I think the most important can be seen in the global plot below.
This represents a map connecting people through chemicals. The large top right structure represents the connections within the UsefulChem project and the main circle represents the activity of graduate student Khalid Mirza who was the most active on this project. The crescent structure to the right of the circle represents other students - mainly undergraduates - who worked with the same chemicals as Khalid.

At the top left there are 3 isolated small networks, representing completely separate projects: the sodium hydride (NaH) oxidation study, Dustin Sprouse and Sebastian Petrik. I'll be posting about Sebastian's work in a future post.
Near the bottom middle there is another small network connected to the main group by a single link mediated by 2,2-dimethoxyethylamine.

This represents the overlap between Open Notebooks (Wolfle from Todd group and Mirza from Bradley group) that I mentioned previously.

I think that automatically discovering such connections as they occur could be a really useful outcome of this network analysis work. For example, the researchers could be alerted by email that a new potentially interesting overlap between their projects now exists. This could accelerate new collaborations.
A key challenge in Don's work is to figure out the right questions so that the results will be genuinely useful and novel to the researchers involved and the research community. I'm optimistic that he will succeed. As a separate outcome, just learning how researchers collaborate and record their work over time is bound to be interesting.
For a description of Don's planned work over the next several months take a look at his full Thesis Proposal: "Proposal of a System and Methods for Integrating Literature and Data".

Chemical Information Validation Results from Fall 2010

As I mentioned earlier, one of the outcomes from my Fall 2010 Chemical Information Retrieval class involved the collection of chemical property information from different sources in a database format. Now that the course is over, this has resulted in 567 measurements for 24 compounds (including one compound EGCG from the previous term). I have curated the dataset to ensure that the original numbers, conversions to common units, categorizations, etc. are correct. Links to the information source or to a screenshot of the source are available for each entry - so if I missed something, anyone can unambiguously verify it for correction.

The dataset is available from a Google Spreadsheet. Andrew Lang has also created a web based interface: the ChemInfo Validation Explorer. By simply specifying the compound of interest and the property using drop-down menus the list of measurements from the relevant sources is provided with values outside of one standard deviation marked in orange. Links to the information source, or an image in cases where the information source cannot be directly linked, are provided in the results. Here is an example for the boiling point of benzene.

The visualization and analysis of the data was greatly facilitated by the use of Tableau Public. After downloading the free program anyone can easily re-create the queries in this post by first downloading the dataset as an Excel document then importing into Tableau Public. Interactive charts can then be freely hosted on the TP server and embedded as I have done in this post below.

The students were shown how to search both commercial and free information sources and were given complete freedom for which compounds and chemical properties to target. The results can be analyzed from the perspective of a reasonable sampling of the current state of chemical information available to the average chemist. The 5 most frequently obtained properties were melting point, density, boiling point, flash point and refractive index.

Sheet 1
Sheet 1

The information sources were categorized and are reported below by frequency. Chemical vendor sites were by far the most frequently used information source.
Sheet 1
Sheet 1

It is important to note that the information source does not represent the method by which the measurements were found. The source is simply the end of the chain of provenance: the document that provides no specific reference for the reported measurement. For example, even though ChemSpider was frequently used as a search engine, it would not be listed as an information source when it provided links to other sources (mainly MSDS sheets) for properties. ChemSpider was treated as a source for some predicted properties.

Sheet 1
Sheet 1

The chemical vendor Sigma-Aldrich was the most frequently used information source, followed by Alfa Aesar. Wolfram Alpha - categorized as a "free database" was third. Oxford University follows closely behind as fourth and is categorized as an "academic website", hosting MSDS sheets. Many universities host MSDS sheets but the Oxford web site seems to turn up most frequently from chemical property queries on search engines.

The fifth most frequent information source was Wikipedia, reflecting the fact that specific references are usually not provided there for chemical properties. Like ChemSpider, Wikipedia was categorized as a "crowdsourced database".

Flagging Outliers

One of the advantages of this type of collection is that it is much easier to identify outliers. In the case of non-aqueous solubility data, we were able to create an outlier bot to automatically flag potentially problematic results. Since different properties may have very different typical variabilities, outliers are most easily discovered by comparisons within the same property.

For example consider the following plot showing the standard deviation to mean ratio for melting point measurements.

Sheet 1
Sheet 1

This reveals that the average melting point for EGCG is suspect. At this point, an easy way to inspect the results is to use the Validation Explorer and look at the individual measurements.

By clicking on the images we can verify that the numbers have been correctly copied from the primary sources. In this case we can also ascertain that the sources - a peer reviewed paper and the Merck Index - are considered by most chemists to be generally reliable. There is no compelling reason at this point to weigh one result over the other and one has to be careful when using the average value for any practical application. (Note that all temperature data is recorded as Kelvin. A zero-based scale is necessary to ensure that the standard deviation to mean ratio is meaningful.)

The next flagging hit in this collection is the melting point of cyclohexanone. In this case 5 results are returned and the Validation Explorer highlights the Alfa Aesar value as being more than one standard deviation from the average.

However, one has to be careful when assessing this and assuming that the Alfa Aesar value is most likely to being the odd value out. Notice that 3 of the values - Sigma-Aldrich, Acros and Wolfram Alpha are identical. The most likely explanation for this is that all three used the same information source and should thus be counted as a single measurement.

We can test this hypothesis by looking for cases where Sigma-Aldrich, Acros and Wolfram Alpha don't share identical values. As shown below, for melting point measurements, there is no case where the values don't match.


The same is true for boiling points:

However, in the case of flash points it is clear that the three are not using a common data source.


Using the data we collected - and will continue to collect - we could start to identify which data sources are likely using the same ultimate sources and avoid over-counting measurements. This would save time in searching since one would know which sources to check for a particular property while avoiding duplication. This information is extremely difficult to obtain using other approaches.

The same type of outlier analysis can be performed for all the properties collected in this study.

I believe that there is much more useful analysis to be done on this dataset, especially for chemistry librarians. When this class is run next year, more data will be added. In the meantime, contributions from other sources would be welcome.

Nanoinformatics 2010 Conference Report

On November 3, 2010 I presented on "The implications of Open Notebook Science and other new forms of scientific communication for Nanoinformatics" at the Nanoinformatics 2010 conference.

The presentation first covers the use of the laboratory knowledge management system SMIRP for nanotechnology applications during the period of 1999-2001 at Drexel University. The exporting of single experiments from SMIRP and publication to the Chemistry Preprint Archive is then described followed by the evolution to Open Notebook Science in 2005. Abstraction of semantic structure from ONS projects in the areas of drug discovery and solubility is then detailed as an efficient mechanism to provide web services and machine readable data feeds.
This was a terrific opportunity to tie together my current ONS projects with my work in nanotechnology about 10 years ago, when the focus was to capture laboratory information in a structured format so that autonomous agent could begin to replace human workflows. I found it really interesting that the most active workflows back then were related to processing reference information. It took a team of students to find, photocopy and scan many of our key papers, with all the problems that come with training and managing new students. Today, obtaining relevant papers and extracting metadata is not so much of a challenge with tools like Mendeley. I ended the talk with a mention of our use of Mendeley tags to share dynamic links of article collections.
Another important development over the course of the past decade is the availability of free and hosted tools to easily communicate research. This includes wikis, blogs, Nature Precedings, institutional repositories, Google Spreadsheets and many others. It also includes some failed attempts like the Chemistry Preprint Archive.
I didn't anticipate in the late 90s just how crucial openness would prove to be for the evolution of the automation of the scientific process. It isn't my impression that there is currently a consensus on this point. Obviously it is possible to leverage automation in very clever ways for private use. But I think that exponential impact requires very low barriers to contribution (human or not) that can only be achieved with openness and transparency.
I have been very impressed with the ideas and projects discussed at this conference. Open sharing of nanotechnology data and integration of resources are clearly high priority items for many in this community.
As we have shown with our Reaction Attempts and ONS Solubility projects, abstracting meaningful semantic structure is necessarily field specific. One of the exciting opportunities to result from this meeting is finding ways to interconnect our solubility dataset with the nanotechnology community resources. I have met with a few people who would like to collaborate on this and I will be sure to report on our progress.

Dana Vanderwall on Cheminformatics at Drexel

Dana Vanderwall, Associate Director of Cheminformatics at Bristol-Myers Squibb, presented for my last Chemical Information Retrieval class on December 2, 2010.
The first part covered "Cheminformatics & The evolving relationship between data in the public domain & pharma" and included a general discussion of modern drug discovery and the details of a malaria dataset recently released from the pharmaceutical industry to the public.
The second part described a project based on "Molecular Clinical Safety Intelligence", where tracking side effects from approved drugs can help in the design of new drugs.
It was a very nice way to close out the course, showing very practical applications of the concepts we covered over the term. The recording is available below.

The Meaning of Data panel at a class on the Rhetoric of Science

Update: Lawrence Souder provided the audio for the presentation and panel questions.

On October 6, 2010 I had the pleasure to participate in a panel discussion at Lawrence Souder's class on the Rhetoric of Science. I gave a brief presentation on "The Meaning of Data" to kick off the discussion. I provided a scientist's perspective of data - with the basic idea that at best data are evidence. Data cannot be treated as irrefutable facts since there is always some uncertainty and many assumptions must be made in their interpretation. I also argued that, although uncertainty cannot be eliminated completely, transparency goes a long way to reducing it.

The students in the class did not have a science background and I think it was informative for them to explore a different perspective from their other exposure to science through popular media or even textbooks. The term "fact" is thrown around a lot in these information sources to simplify but it doesn't reflect how scientists think about data. We discussed how unbelievably wrong the scientific details in movies and TV shows such as NCIS and House can be. Nevertheless, one student pointed out that these shows can be effective in attracting people to science - as long as it was understood that the details were probably incorrect.
Because of market forces we recognized that science portrayed in the popular media would have a strong tendency to be exaggerated or oversimplified resulting in the phenomenon of "hype". A related effect can distort the way scientists communicate with each other, where there is a perception that exposing ambivalence in the form of seemingly contradictory data may not be in the researcher's best interest. This is a strong deterrent to the general adoption of transparency.
We explored the possible evolution of scientific communication as new tools such as blogs and wikis become increasingly used by scientists. Of course the issue of claims of priority was brought up and I discussed how this issue was handled in my own research work.
We debated whether these new forms of communication would alter the language used in scientific communication - even in traditional journals. I think that with the advent of the semantic web many researchers will start to write in a way that is understandable to humans as well as machines, their new target audience. One student remarked that the new generation coming up is very used to texting and that type of succinct communication is certainly in line with machine readability.
The assigned reading for the class involved a study of the language used by the Nobel laureates who discovered the buckyball to describe their research:

"In Praise of Carbon, In Praise of Science - The Epideictic Rhetoric of the 1996 Nobel Lectures in Chemistry by Christian Casper". This paper demonstrates that both personality and the perceived target audience can dramatically affect the language and focus that scientists use to explain their research.

Dynamic links to private tagged Mendeley collections

My close collaborators and I have been using Mendeley as a convenient way to share PDFs of journal articles. Not all of us have access to the same libraries so links are not enough - we need the full documents. We also use Dropbox as a redundancy but Mendeley allows tagging and recording notes, which is very handy for everyone in the group.

Now that Mendeley is providing an API, Andrew Lang has written code that significantly leverages the information in our private ONS collection. We can now create public links that return the most updated results for specific tags, including multiple tags (which I don't think you can do on Mendeley). For example the following link returns all articles in the ONS collection tagged with "science2.0" and "chemistry":

The results include available information from Mendeley, including the title, authors, journal citation, doi, url, tags and the abstract. Because this information is public the PDFs can't be provided but the hyperlinks make it as convenient as possible.

At the end of the report the full list of all available tags for the ONS collection is provided. A more refined or different search can be done immediately simply by checking boxes and hitting the submit button.Because the tags are controlled by the users of the private collection, these links can be useful when discussing an ongoing project and referring to a very specific topic. For example, we have been collecting examples of articles where a Ugi reaction is carried out and the product precipitates. This link provides an updated report on that very narrow topic:

http://showme.physics.drexel.edu/onsc/mendeley/?tags=Ugi+precipitate

There are still 2 major limitations to this service:

1) The search is very slow (can take a minute or two) because there is no way currently to use the Mendeley API to selectively return results based on tags. Every search requires initially returning all results for the collection (currently a few hundred).
2) Notes are currently not returned. If the API is updated to include these the usefulness would increase dramatically. For example in the results for the above query I took notes of the conditions involved in the Ugi precipitate for each paper. With the current format, one has to read each paper to find the relevant information.
Progress on our Mendeley related services will be posted on the ONSwebservices wiki.

Elizabeth Brown’s guest lecture for ChemInfo Retrieval

Elizabeth Brown from the Binghamton University Libraries presented on "Web 0.0/1.0/2.0/3.0 and Chemical Information" on October 21, 2010 as a guest lecturer for my fifth class on Chemical Information Retrieval this term.

Beth made an interesting analogy with art to illustrate the differences between these communication platforms. What stuck me during her presentation was the similarity between the current state of the semantic web (Web3.0) and the state of computerized searching in chemistry when I was a graduate student in the early 90s. I had the chance to do just one substructure search at the time and it had to be done through an expert librarian. The search had to be carefully planned because of the expense.

From what I recall, the perception at the time was that computerized searching was impractical and perhaps even unnecessary. After all "the way" to search for chemical information was to spend a weekend in the library systematically going through Chemical Abstracts books. This had "worked" for long time for the chemistry community and doing things differently was considered superfluous and even wasteful.

Today, "the way" to search for chemical information is to use expensive databases to perform a targeted search and extract the information from mainly toll access peer reviewed journals. If you are off the academic grid you have to rely on free information on the web which is rarely associated with a chain of provenance. As my students will attest, even with access to the best tools, it still takes a lot of time to find the information and compare it for consistency.

The unfamiliarity with computerized searching in the early 90s is now the common attitude towards the semantic web. This is understandable because its availability is limited and people don't understand what to do with the tools that are available. Web services that we provide (derived from other services from ChemSpider and other sources) are usable by anyone who can open up a Google Spreadsheet and copy and paste a URL but it will take time for people to understand how to incorporate these into their workflows.

I think that in 10 years the semantic web will simply be part of the infrastructure. Currently, when you type a word in a browser or word processing software the system knows enough to alert you to possible misspelling by underlining a word. Similarly, in the near future, typing or specifying in some way a chemical compound will automatically pull in all relevant measured or calculated properties and provide suggestions in the context of a chemical reaction under consideration. Access to information will be free and unencumbered and the chain of provenance will be clear.

Instead of taking hours to find and process property data for single compounds, I think students in the future will be handling large libraries of compounds, looking for the best synthetic targets for their applications.

Open Notebook Science in Drug Discovery at Opal Event

I presented on "Open Notebook Science in Drug Discovery" on August 24, 2010 at a panel on Industry and Academia part of the Opal Event "Drug Discovery: Easing the Bottleneck".

I only had about 15 minutes to present so I could not go into much detail but I did want to highlight the most recent work Andrew Lang and I (also with Peter Li from ChemTaverna) carried out involving solubility prediction and web services. Most of the attendees were from industry and I appropriately used the recent GSK malaria data sharing to introduce the talk. It is clear that there is a role for Open Science in drug discovery and I think that industry involvement will continue to increase in this area.

My co-panelist Rathindra Bose from Ohio University presented on his group's development of a novel cancer treatment compound based on platinum. He made the point that academic research complements that from industry by being able to explore more speculative hypotheses. The dominant hypothesis for the mechanism of action of platinum based drugs is binding with DNA. By exploring alternative scenarios, his group found an active platinum drug that does not bind with DNA.
During the preceding session on the Emergence of Biologics in Drug Discovery, Albert Giovanella from the University of Pennsylvania School of Medicine gave a particularly enlightening talk about comparing biologics with small molecule drugs. Although biological drugs tend to have less toxicity, the overall cost to bring them to market is still quite high and their cost to the consumer may be so high as to limit their impact. It looks like it will not be generally easy to translate new biomedical knowledge to a widespread impact on human health.

Cheminfo Retrieval Classes 1 and 2 in 2010

My first Chemical Information Retrieval class for the Fall of 2010 took place on Sept 23, 2010. This is the second time that I've taught the class as sole instructor and it was certainly convenient to have last year's wiki to build upon. The assignments are the same so it was helpful to be able to give students access to what students did last year as examples.

The key message from my introductory lecture was that it can be really difficult to find usable chemical information and that there are no shortcuts like relying on a true trusted source - those don't exist. I showed a few examples of emerging models - Open Access, Open Notebook Science, Collaborative Competition (like pharma companies sharing some drug data openly) and other Open Science initiatives.
I also announced that we would be doing something new in the Science3.0 theme (the semantic web). One of the assignments involves collecting 5 values from the literature for each of 5 properties for a compound of the student's choice. In addition to adding these values on the wiki, we will collect them in a format that is friendly to machines: a ChemInfo Validation Google Spreadsheet. Andrew Lang has agreed to help with adapting our previous code for solubility to creating web services for this application. For example, we can have a service that reports the mean and standard deviation for a particular property and chemical. Another could produce statistics for a given data source or compare peer reviewed vs non peer reviewed sources, etc. Since it will be possible to to call these web services from within a Google Spreadsheet or Excel it should enable much more sophisticated analysis of the data related to the "validity" of chemical information as it exists today.
I didn't record the first lecture but I have the slides below:

During the second lecture on September 30, 2010 I spent most of the time showing students how to use Beilstein Crossfire, SciFinder and ChemSpider to find values for chemical properties. The recording for the second lecture is available below:

IGERT NSF panel on Digital Science

On May 24, 2010 I was part of a panel in Washington for the NSF IGERT annual meeting. As I mentioned previously, it is encouraging to find that funding agencies are paying more attention to the role of new forms of scholarship and dissemination of scientific information.

My co-panelists included Janet Stemwedel, who talked about the role of blogging in an academic career, Moshe Pritzker, who made a case for using video to communicate protocols in life sciences and Chris Impey, who demonstrated applications of clickers and Second Life in the classroom.

We only had 10 minutes each to speak so the presentations were basically highlights of what is possible. Still, it was enough to stimulate a vigorous discussion with the audience. There was a bit of controversy about the examples I used to demonstrate the limitations of peer review in chemistry. People can misinterpret what we are trying to do with ONS - it certainly doesn't include bringing down the peer review system (not that we could anyway). But we have to face the situation that peer review does not validate all the data and statements in a paper. It operates at a much higher level of abstraction. Providing transparency to the raw data should work in a synergistic way with the existing system.

My favorite part of the conference was easily Seth Shulman's talk on the "Telephone Gambit". Ever since reading his book, I have been using the story of how carefully reading Bell's lab notebook has forced us to revise the generally accepted notion of how the telephone was invented. Seth's presentation was truly captivating because he explained not only what was done but also what motives were at work to deceive and obfuscate. This cautionary tale is still very much relevant to science and invention today - and highlights how transparency can mitigate against this type of outcome.

Reaction Attempts Explorer

Two months ago I reported on the Reaction Attempts project and the availability of the summary as a physical or electronic (PDF) book. The basic idea behind the project is to collect organic chemistry reaction attempts reported in Open Notebooks. This would include not only successful experiments but also those which could be categorized as failed, ambiguous, in progress, etc.

The book was organized with reactants listed alphabetically. In this way one could browse through summaries of the types of reactions being attempted by different researchers on a reactant of interest. There might be information there (what to do or what to avoid) of some use for a planned reaction. At the very least one could contact the researcher to initiate a discussion about work that had not yet been published in the traditional system.

Andrew Lang has just created a web-based tool to explore the Reaction Attempts database in much more sophisticated ways.

Here are some scenarios of how one could use it. On the left hand side of the page is a dropdown menu containing an alphabetically sorted list of all the reactants and products in the database. Lets select furfurylamine.


This immediately informs us that there are 230 reactions involving furfurylamine and it lists the schemes for all these reactions upon scrolling down. That's still a bit hard to process so a second dropdown menu appears populated with a list of other reactants or products involved with furfurylamine.

We now select boc-glycine and that narrows our search to 145 reactions.

Selecting benzaldehyde from the third dropdown menu narrows the search further to 61 reactions.

The final dropdown menu contains a short list of only isocyanides and thus all represent attempted Ugi reactions. Selecting t-butyl isocyanide gives us 56 reactions.

That means that these same 4 components were reacted together 56 times. Looking at the various reaction summaries will show that some of these are duplicates for reproducibility and others vary concentration and solvent and the effect on yield is included. This particular reaction was in fact the subject of a paper on the optimization of a Ugi reaction using an automated liquid handler.

Now here is where the design of the Explorer comes in handy. We might want to ask if the reaction proceeds as well with the other isocyanides. All we have to do is switch the final dropdown menu to ask what happens when we go from t-butyl to n-butyl isonitrile. There is a single attempt of this reaction and it is "failed" in the sense that no precipitate was obtained from the reaction mixture. This doesn't mean that the reaction didn't take place - it might be that the Ugi product was too soluble. We can quickly inspect that the concentration and solvent are in line with conditions that allowed precipitation of the t-butyl derivative.

OK lets see what happens with n-pentyl isocyanide.

It looks like it behaves just like n-butyl isocyanide: another single non-precipitation event. What about benzyl isocyanide?

This time we do get the Ugi product from a single attempt. Note the lower yield compared to the t-butyl isocyanide under similar conditions.

What about with cyclohexyl isocyanide?

This time we hit an experiment in progress. A precipitate was obtained but it was not characterized. We can click on the link to the lab notebook page (EXP232) to learn more about how long it took for the precipitate to appear but there are not enough data to draw a definite conclusion about the successs of the reaction. However, based on the results from the other precipitates in this series it is probably encouraging enough to repeat and characterize the product.

There are other sources of information here. Clicking on the image of the Ugi product takes us to its ChemSpider entry. In this case the only associated data relates to this reaction attempt.

Lets look at another scenario: reactions involving aminoacetaldehyde dimethyl acetal.

In this case we find the intersection of two Open Notebooks. The first reaction comes from Michael Wolfle from the Todd group.

The second comes from Khalid Mirza from the Bradley group.

In order to learn more about the nature of the overlap we can use the substructure search capabilities of the Reaction Explorer. Simply click on the image of the acetal and the ChemSpider entry pops up. Now click on the copy button next to the SMILES for the compound.

Paste the SMILES into the SMARTS box of the Reaction Explorer.

We get 13 reaction attempts for this query - the two we found earlier and the rest corresponding to attempts by Michael Wolfle to synthesize praziquanamine.

We learn that one connection between these two notebooks involves different attempts at synthesizing praziquantel.

Hopefully this demonstrates the value of abstracting organic chemistry reaction attempts from Open Notebooks into a machine readable format. Contributions to the database require only the ChemSpider IDs of the reactants and product and a link to the relevant lab notebook page. Reaction schemes are automatically generated by the system. More on the Reaction Attempts project here.

ChemTaverna Workflows of ONS Web Services now on MyExperiment

I'm pleased to report that one of the collaborations initiated at the Berkeley Open Science conference last month is progressing very well.

Carole Goble introduced me to Peter Li who runs the ChemTaverna project. The idea was to use Taverna to construct workflows using the web services developed by Andrew Lang for our Open Notebook Science projects: UsefulChem and the ONS Solubility Challenge.
Peter quickly created several workflows to demonstrate what is possible. Here is a workflow that uses a Google Spreadsheet as input. SMILES for amines, carboxylic acids, aldehydes and isonitriles are entered in the appropriate columns. The workflow first creates a virtual library of Ugi products from all possible combinations of reactants. Then each product is submitted to a web service that predicts the solubility in methanol, the most common solvent for Ugi reactions.

The resulting spreadsheet can then be sorted by predicted solubility to recommend products that are more likely to precipitate from the reaction mixture. In this particular example Ugi products derived from boc-glycine are predicted to have a low solubility in methanol. The least soluble compound is predicted to have a solubility of only 0.07MIn this library, Ugi products derived from boc-methionine are predicted to be too soluble to precipitate. For example this Ugi product has a predicted solubility of 3.7 M.
(note: ChemSpider has a tendency to draw the minor tautomer for some amides and carbamates)

There are a few issues to take into consideration in order to use this particular workflow:
1) This will only work on Taverna Workbench 2.1.2 with these plug-ins installed. At one point it will be made to work on Taverna Workbench 2.2 and uploaded onto MyExperiment. The workflow used here is currently available here.
2) The SMILES in the input Google Spreadsheet must be written in the format of the current example (aldehyde, amine and isonitrile groups on the left and carboxylic acid groups on the right)
3) All of the Ugi products in the virtual library must already exist in ChemSpider. Otherwise, the solubility predictions will fail because of missing descriptors as discussed previously.
Peter has uploaded simpler workflows onto MyExperiment that are compatible with the current version of Taverna Workbench (v2.2).
First, the generation of Ugi product libraries from reactant SMILES in a Google Spreadsheet is available here.

Another workflow handles the prediction of Abraham descriptors.
This workflow processes the prediction of solubility for a given solute and solvent.

The main rationale for incorporating web services derived from our Open Notebook Science projects into Taverna is leverage. MyExperiment already benefits from a vigorous community of developers in the bioinformatics arena. With the growth of the ChemTaverna initiative, the integration of cheminformatics and bioinformatics workflows should become seamless.

By making our solubility and chemical reaction web services available in formats that are convenient for others to use it increases the opportunities that our work will be actually useful. It also makes it easier for us to leverage the resources made available by others for our own applications in drug discovery and reaction design.

Essentially this means that we have extended the reach of the information cascade triggered by the recording of an experiment in a laboratory notebook and a very simple abstraction process to represent that experiment in a semantically addressable format.

ASMS: Anthrax attacks

Ever since the infamous US anthrax attacks of 2001, where envelopes containing anthrax spores were mailed to a number of media outlets and two US Senators, there has been a push to develop new ways of determining the severity of anthrax infections.

John Barr, of the US Centers for Disease Control and Prevention (CDC), has developed a new, more sensitive way of monitoring the level of infection in a victim. This is keenly important as the symptoms for anthrax infection start off looking much like a cold or the flu, but can then lead to a subject deteriorating rapidly – often leading to death, even after treatment. According to Barr some 40 per cent of the victims of the 2001 anthrax letters died.

The Bacillus anthracis bacterium produces two different t toxins, the oedema factor and the lethal factor. Barr has developed a way of detecting both of these using a liquid chromatography – mass spectrometry (LC-MS) approach that can provide earlier diagnosis than any other technique. This is particularly important as providing antibiotics at an early stage in the infection can increase the odds of survival.

His method, which uses an antibody purification step to extract the toxins, can detect the toxins at concentrations as low as 25pg/ml in about two hours. If the antibody extraction step is left for around 16 hours, that detection limit can fall as low as 5 pg/ml.

The progression of the infection tends to go through a brief remission, and the changes in lethal factor levels correlate with the clinical symptoms – and during remission other methods that rely on detecting the bacteria themselves often fail during this stage.

Barr believes his results should enable clinicians to predict the clinical outcome of an infection, which could prove immensely important as there have recently been a number of anthrax poisoning cases in Scotland, after heroin addicts injected themselves with anthrax-contaminated spores.

Matt Wilkinson

This week on Chemistry World…

1 June 2010: Have something to say about an article you’ve read on Chemistry World this week? Leave your comments below…

This week’s stories…

Basic research bill backed in US
US bill that boosts science funding passes on third attempt after Democrats employ unusual procedural tactic

Universities face hard years ahead
Funding cuts to universities across Europe as a result of the economic crisis will impact teaching and research quality for years to come, says report

Structural order gained over conducting polymer
Researchers have used copper as both catalyst and template to gain structural control over an important conducting polymer

Liquid marbles detect gases
Scientists use porous properties of liquid marbles to develop gas sensors

Instant insight: Cosmic dust as chemical factories
Daren Caruana and Katherine Holt discuss how electrochemistry could be the missing link to understanding chemistry in space

Use of ONS to protect Open Research: the case of the Ugi approach to Praziquantel

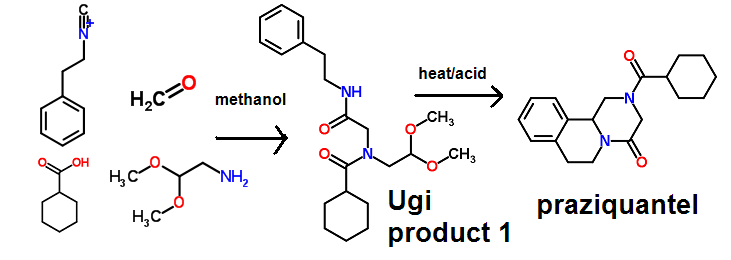
As we were collecting reactions from The Synaptic Leap for the Reaction Attempts project, Andrew Lang noticed that there might be a quick synthetic route to praziquantel via a Ugi reaction. I researched it further and found a paper (Kim et al 1998) where Ugi product 1 was indeed converted to racemic praziquantel via the Pictet-Spegler cyclization.


Using Beilstein Crossfire the only synthesis of 1 I found involves a multi-step amidation strategy. But this compound should be accessible in one step from commercially available starting materials via a Ugi reaction (shown above). Since all the starting materials are liquids we have some flexibility with solvent choice. Khalid first tried it in methanol EXP258 a few weeks ago but did not get a precipitate. He was going to monitor it by NMR next to see if the problem was high solubility of the Ugi product or with the reaction itself.

It was therefore with great interest that I read Mat Todd's report this morning on The Synaptic Leap that a German patent had been issued on this Ugi strategy to praziquantel. (TSL didn't provide a means of leaving a comment so I edited the page - which made me the author of that post but actually Mat wrote it)

I have often mentioned during my talks that Open Notebook Science could be used not only in a defensive manner to claim academic priority - but also as an offensive tactic to block patent applications. A company attempting to prevent the commercial exploitation of rival inventions has a few options. Where applicable, it can buy up an existing patent pool with the intention of sitting on it. For new inventions, it can do research and try to file patents before their competitors. But this is a costly process and it may make more sense to simply publish the inventions to create disclosed prior art, thereby blocking patent applications of their competitors.

But - as I and many others have discussed - the current publication system is not optimally suited for the purpose of simply disclosing and communicating science. Not only is it generally slow but the traditional article format requires a narrative of some sort - rarely can single experiments be published. This means that much (if not most) of research done by an individual or group will never be disclosed.

For these reasons I think that keeping an easily discoverable Open Notebook for projects designed to block patent submission by competitors makes a lot of sense - both economically and from a workflow perspective. Since researchers already have to keep a lab notebook, making it public doesn't impose the added time that writing an article or patent will require.

In this specific example of praziquantel we were too late. But if we had recorded this experiment a few years ago it might have worked to block Domling's patent. Now, it isn't clear to me that EXP258 would have been enough to do that. The strategy to make praziquantel via a Ugi reaction was clearly stated but the experiment was not conclusive. However, since Domling reported that methanol worked I am sure that we would have had the "reduced to practice" evidence in the notebook shortly.

Above I used a company as an example of a party motivated to disclose inventions to protect their interests. In our case it would not be a company but rather the entire Open Science community. It is in our best interest to keep our scientific territory as unencumbered by patents as possible. Keeping Open Notebooks might be one of the simplest means of ensuring that.

Consider a humanitarian organization that might want to manufacture praziquantel. I haven't researched it but presumably the Domling patent was filed in a number of countries beside Germany. In order to consider using the Ugi strategy, the organization would now have to deal with the patent holder. This might be the factor that makes this route untenable. Patents have proven to be problematic for humanitarian aid - even in the simple case of providing food.

But all is not lost. In addition to offering a simple 2-step synthesis of praziqantel, the Ugi route offers an easy way to make large libraries of analogs. Optimally we would like to work with someone who has experience with docking praziquantel. It might be interesting to screen not only the praziquantel analogs but also the uncyclized Ugi products themselves. When we did this for malarial enoyl reductase inhibitors (D-EXP005) we found that we did not need to cyclize to obtain compounds predicted to bind. This ultimately led to active compounds.

The Reaction Attempts Solvent Selector

The ONS Solubility Challenge and the Reaction Attempts project have now been integrated with code written by Andrew Lang to the point that recommendations for solvents are just a click away.

First use the Reaction Attempts Explorer either using the drop-down menus or substructure search as described previously. When a reaction of interest is identified just click on the the link for "Optimal Solvent Prediction".
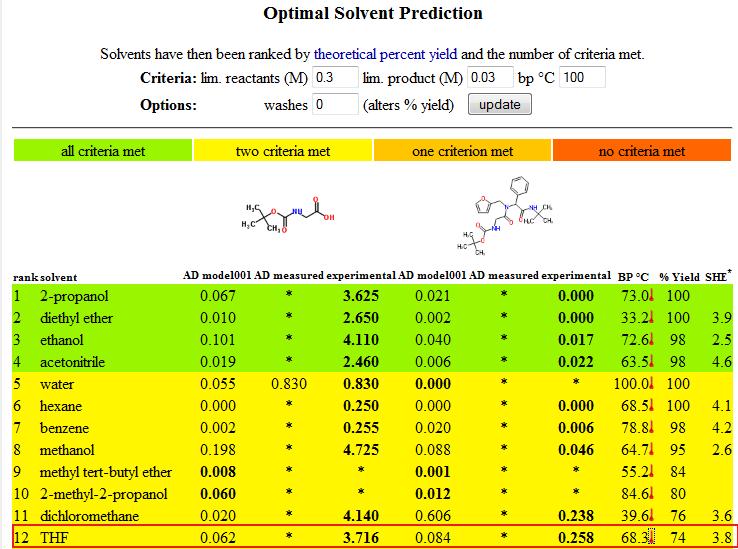
The service will then provide a summary of solubility measurements and predictions, organized by the default criteria of minimum 0.3 M solubility of reactants, maximum 0.03 M solubility of the product and maximum solvent boiling point of 100 C. Liquid reactants (or reactants with melting points within 15 C of room temperature) are excluded since these generally have a high enough solubility in most solvents.
In the case of the Ugi reaction in this example, only the solubility of boc-glycine and the product are considered.

The results are color-coded. In this case 14 solvents are coded green, indicating that all criteria were met. The fifteenth solvent is coded yellow, indicating that one of the criteria was not met - in this case the boiling point of 205 C is outside of the limit of 100 C. High boiling point solvents are not optimal for quickly obtaining the product as a dry solid after filtering. This criterion can be changed in the input fields at the top of the page. It is also possible to change the number of times the product is washed there. This will only change the estimated yield, which is based on carrying out the reaction at the concentration of the least soluble reactant, up to 1 M.

Three columns are generated for the product and each reactant. The column on the right is the average of all measurements, as recorded in the SolubilitiesSum Spreadsheet. The middle column is a solubility prediction based on Abraham descriptors derived from experimental values, as described and used in the ONS Solubility Challenge book. The column on the left contains predictions from the Abraham001 model, which is based on calculated molecular descriptors only.
The numbers in bold represent the best solubility value available for each solvent. If a measurement is known, that will be the number used. If no measurement is available, the experimental Abraham descriptor model is used. If neither of these are available the predictions from the Abraham001 model are used by default.
From the list of solvents in the green section we find ethanol and acetonitrile. Both of these solvents were tried (as mixtures with methanol) in the optimization of this reaction (Bradley et al JoVE 2008) and provided good to intermediate results. THF was found to give low yields for this reaction and it scores at #51 in the yellow section, with a high solubility of the product accounting for the missed criterion.
One should keep in mind that this is just a tool to flag potentially interesting solvents. Common chemical sense needs to be used as well. For example, acetone and butanone are listed in the green section but these are incompatible with the Ugi reaction since they would compete with the aldehyde.
Note that the predictive models are way off in some cases. For example the Abraham001 model dramatically underestimates the solubilities of boc-glycine in the green section, while the measured Abraham descriptor model does much better for these cases. We will prioritize our next solubility measurements to try to improve the models - or at least understand what types of compounds are most likely to yield useful solubility estimates from these models.
In addition to being called from the Reaction Attempts Explorer, the Solvent Selector can be used for any compounds that have ChemSpider IDs. Simply separate the CSIDs with the pipe character:
After modifying the criteria and hitting update, the new criteria are conveniently represented in the URL in this format, making sharing a specific search with anyone easy:
It is even possible to use the service listing just one compound's CSID - this is useful for quickly comparing the measured solubilities with predictions from both models:

Green Solvent Metric on Solvent Predictor

In the spirit of contributing to Peter Murray-Rust's initiative to collect Green Chemistry information, Andrew Lang and I have added a green solvent metric for 28 of the 72 solvents we include in our Solvent Selector service. The scale represents the combined contributions for Safety, Health and Environment (SHE) as calculated by ETH Zurich.

For example consider the following Ugi reaction solvent selection. Using the default thresholds, 6 solvents are proposed and 5 have SHE values. Assuming there are no additional selection factors, a chemist might start with ethyl acetate with a SHE value of 2.9 rather than acetonitrile with a value of 4.6.

Individual values of Safety, Health and Environment for each solvent are available from the ETH tool. We are just including the sum of the three out of convenience.

Note that the license for using the data from this tool requires citing this reference:
Koller, G., U. Fischer, and K. Hungerbühler, (2000). Assessing Safety, Health and Environmental Impact during Early Process Development. Industrial & Engineering Chemistry Research 39: 960-972.

Resveratrol Thesis on Reaction Attempts

A few days ago Andrew Lang suggested to Dustin Sprouse that he submit his thesis to the Reaction Attempts database. Like many undergraduates Dustin put in a lot of time and effort in doing experiments and writing up his results but didn't have quite enough time to obtain all that would have been required for a traditional publication.

A thesis is an unusual document within the context of scientific communication. Unlike a peer reviewed paper, it may contain a large number of "failed experiments" and a substantial amount of speculation. Although it is not quite as detailed as lab notebook, there is often plenty of raw data and details about how failed or ambiguous experiments proceeded.
In Dustin's case we felt that there was enough information provided to include his thesis in Reaction Attempts. In addition, his thesis was accepted by Nature Precedings, thus providing a convenient means of citation.
The first component of the Reaction Attempts project is to quickly abstract the most basic information from synthetic organic chemistry reactions. This includes the ChemSpiderIDs and SMILES from the reactants and target products and brief notes about conditions and outcomes. We are especially interested in failed or ambiguous experiments because these have almost no chance of being communicated and indexed in the traditional systems. When attempting to carry out a reaction, it can be just as useful to know what doesn't work - and more specifically how it doesn't work.
The second component of the project is dissemination. Because the information is encoded semantically, it can be automatically converted to both human and machine readable formats.
One human interface consists of a PDF book (also as a hard copy), with the option of selected reactions specified by listing CSIDs of reactants in the URL. For example Dustin's reactions can be presented selectively here. We also have a Reaction Explorer, where reactants or products can be selected from a dropdown menu or via a substructure search.
We also provide live XML feeds so that others can create applications easily from machine readable data. For example one could create reaction chains automatically, which will occur whenever we enter reactions from multi-step syntheses like Dustin's - based on the synthesis of resveratrol.
I know that Peter Murray-Rust has been very active in automatically abstracting information from chemistry theses. It would be interesting to see how that approach would work for this thesis, especially with the failed experiments. Reducing a page or two of text into only the most salient bits of information manually required a level of judgement that I imagine would be tricky to do automatically.